
Built on Open Standards
A cloud-native architecture designed for enterprise scale, security, and interoperability.
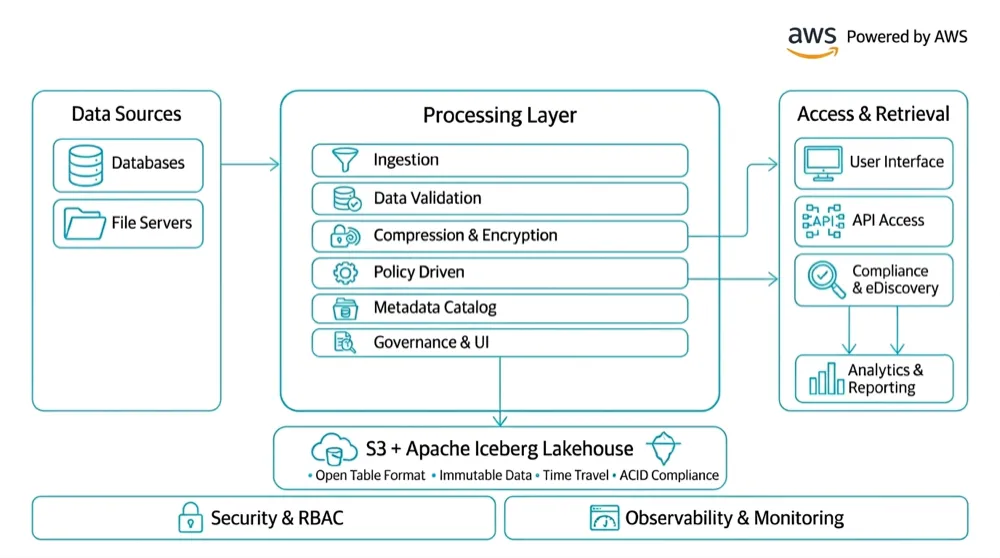
How Data Moves Through ArchiveHouse
From source systems through governed pipelines into a queryable, compliant archive.
Source Systems
Oracle, SQL Server, PostgreSQL, MySQL databases
Ingestion Layer
AWS Glue (Apache Spark) for batch extraction and transformation
Policy & Orchestration
Policy engine, AWS Step Functions, retention rules, validation checks
Archive Storage
Amazon S3 + Apache Iceberg, partitioned, compressed, encrypted
Metadata Service
Schema discovery, connection management, entity catalog
Query & Access
Amazon Athena SQL queries, QuickSight dashboards
Enterprise-Grade Components
Apache Iceberg
Open table format for massive analytic datasets with ACID transactions and schema evolution.
Amazon S3
Durable, cost-effective object storage with 99.999999999% durability.
AWS Glue (Spark)
Managed Apache Spark for high-throughput ingestion and transformation.
AWS Step Functions
Workflow orchestration for scheduling and monitoring archive pipelines.
Amazon Athena
Serverless SQL query engine for interactive queries against archived data.
AWS Cognito & IAM
Authentication, authorization, and fine-grained access control.