
The Complete Data Archiving Platform
Purpose-built for enterprise teams that need to move cold data out of production — without losing compliance, governance, or query access.
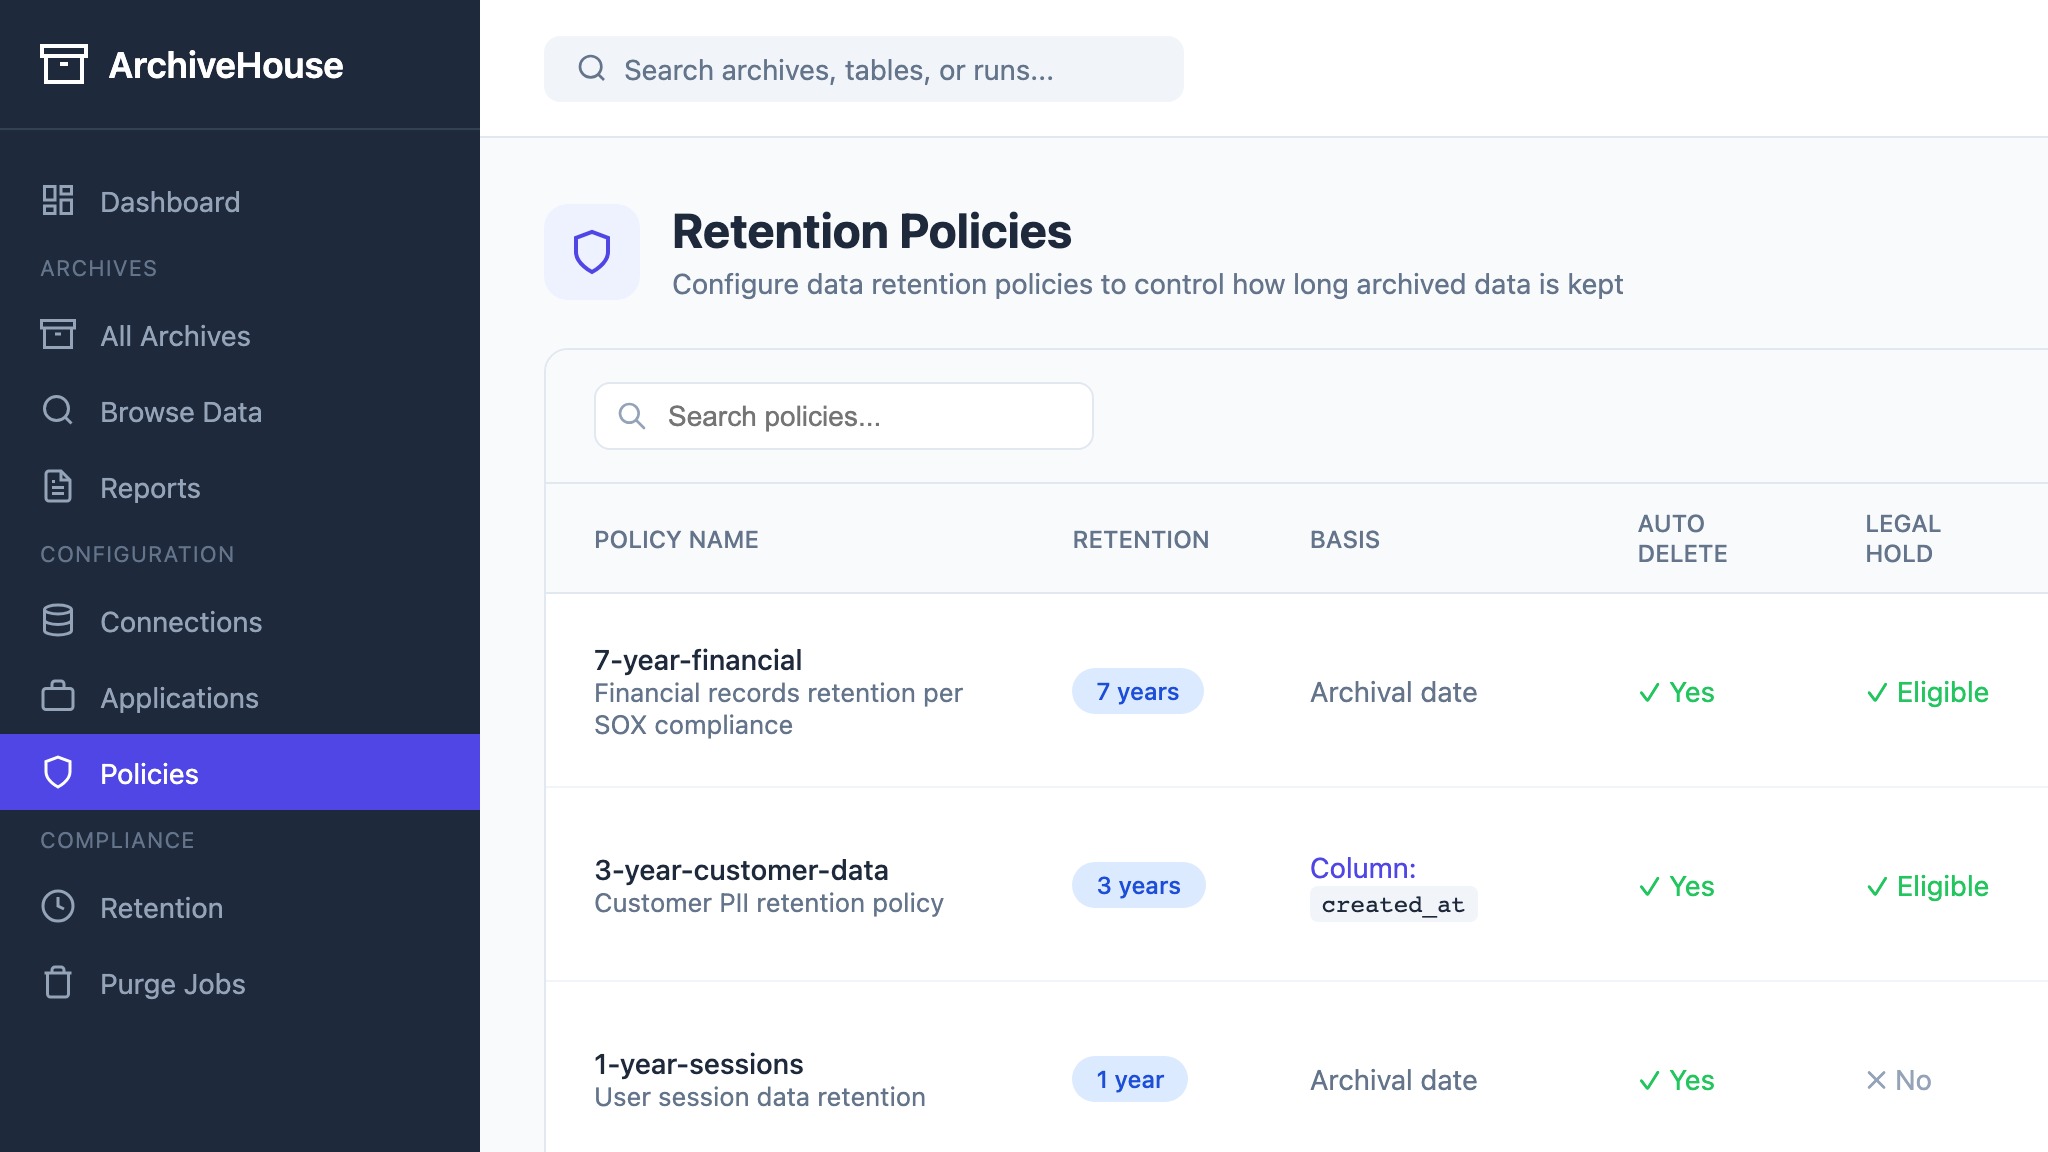
Policy Engine
Define archival policies based on data age and retention requirements. Configure policies per entity with full audit tracking.
- Time-based retention triggers
- Per-entity policy assignment
- Legal hold enforcement
- Policy audit trail
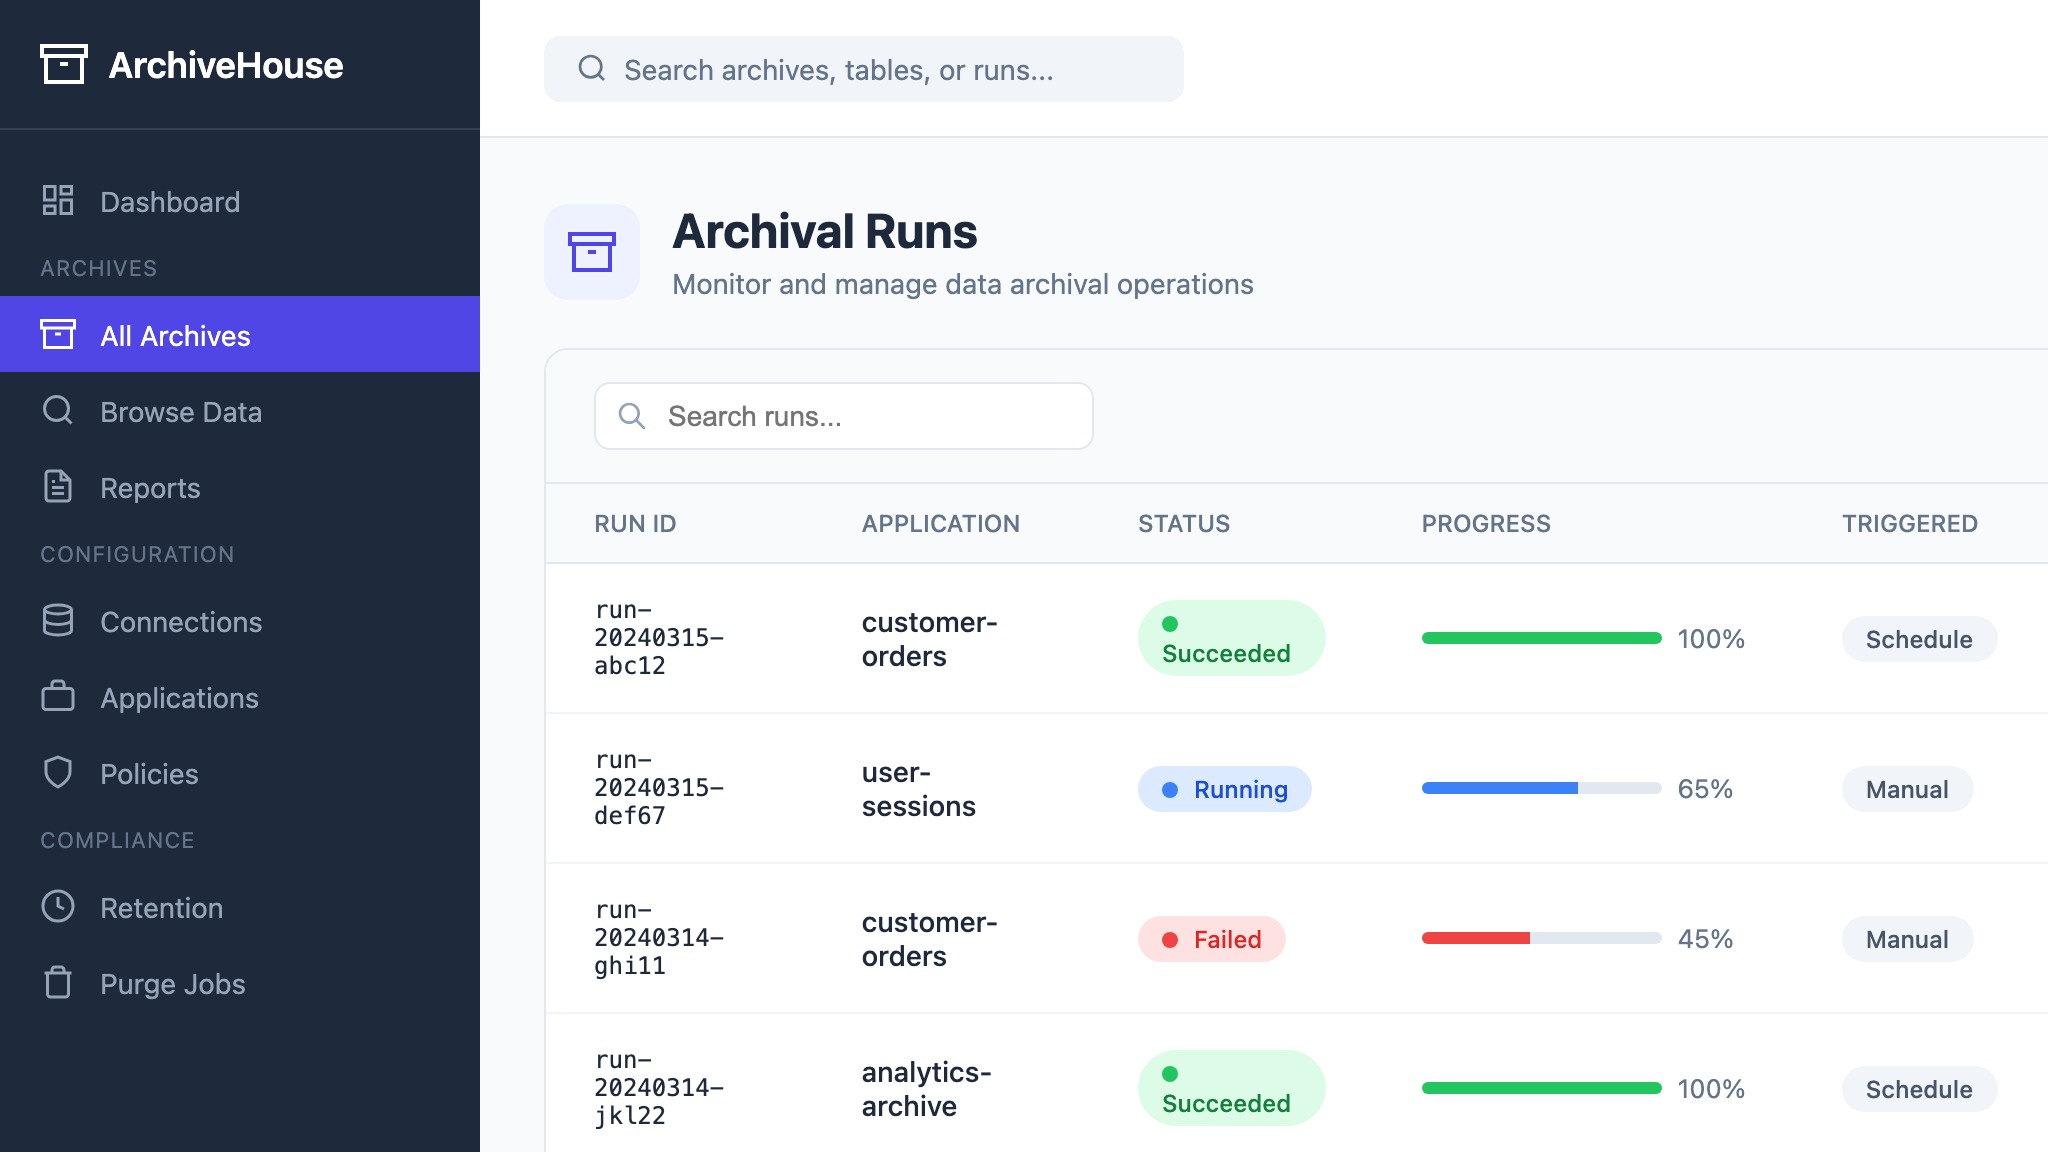
Ingestion Pipelines
High-throughput batch data ingestion from Oracle, SQL Server, PostgreSQL, and MySQL. Built on AWS Glue (Spark) for reliable large-scale transfers.
- Batch extraction mode
- Parallel Glue job execution
- Data validation & checksums
- Row count verification
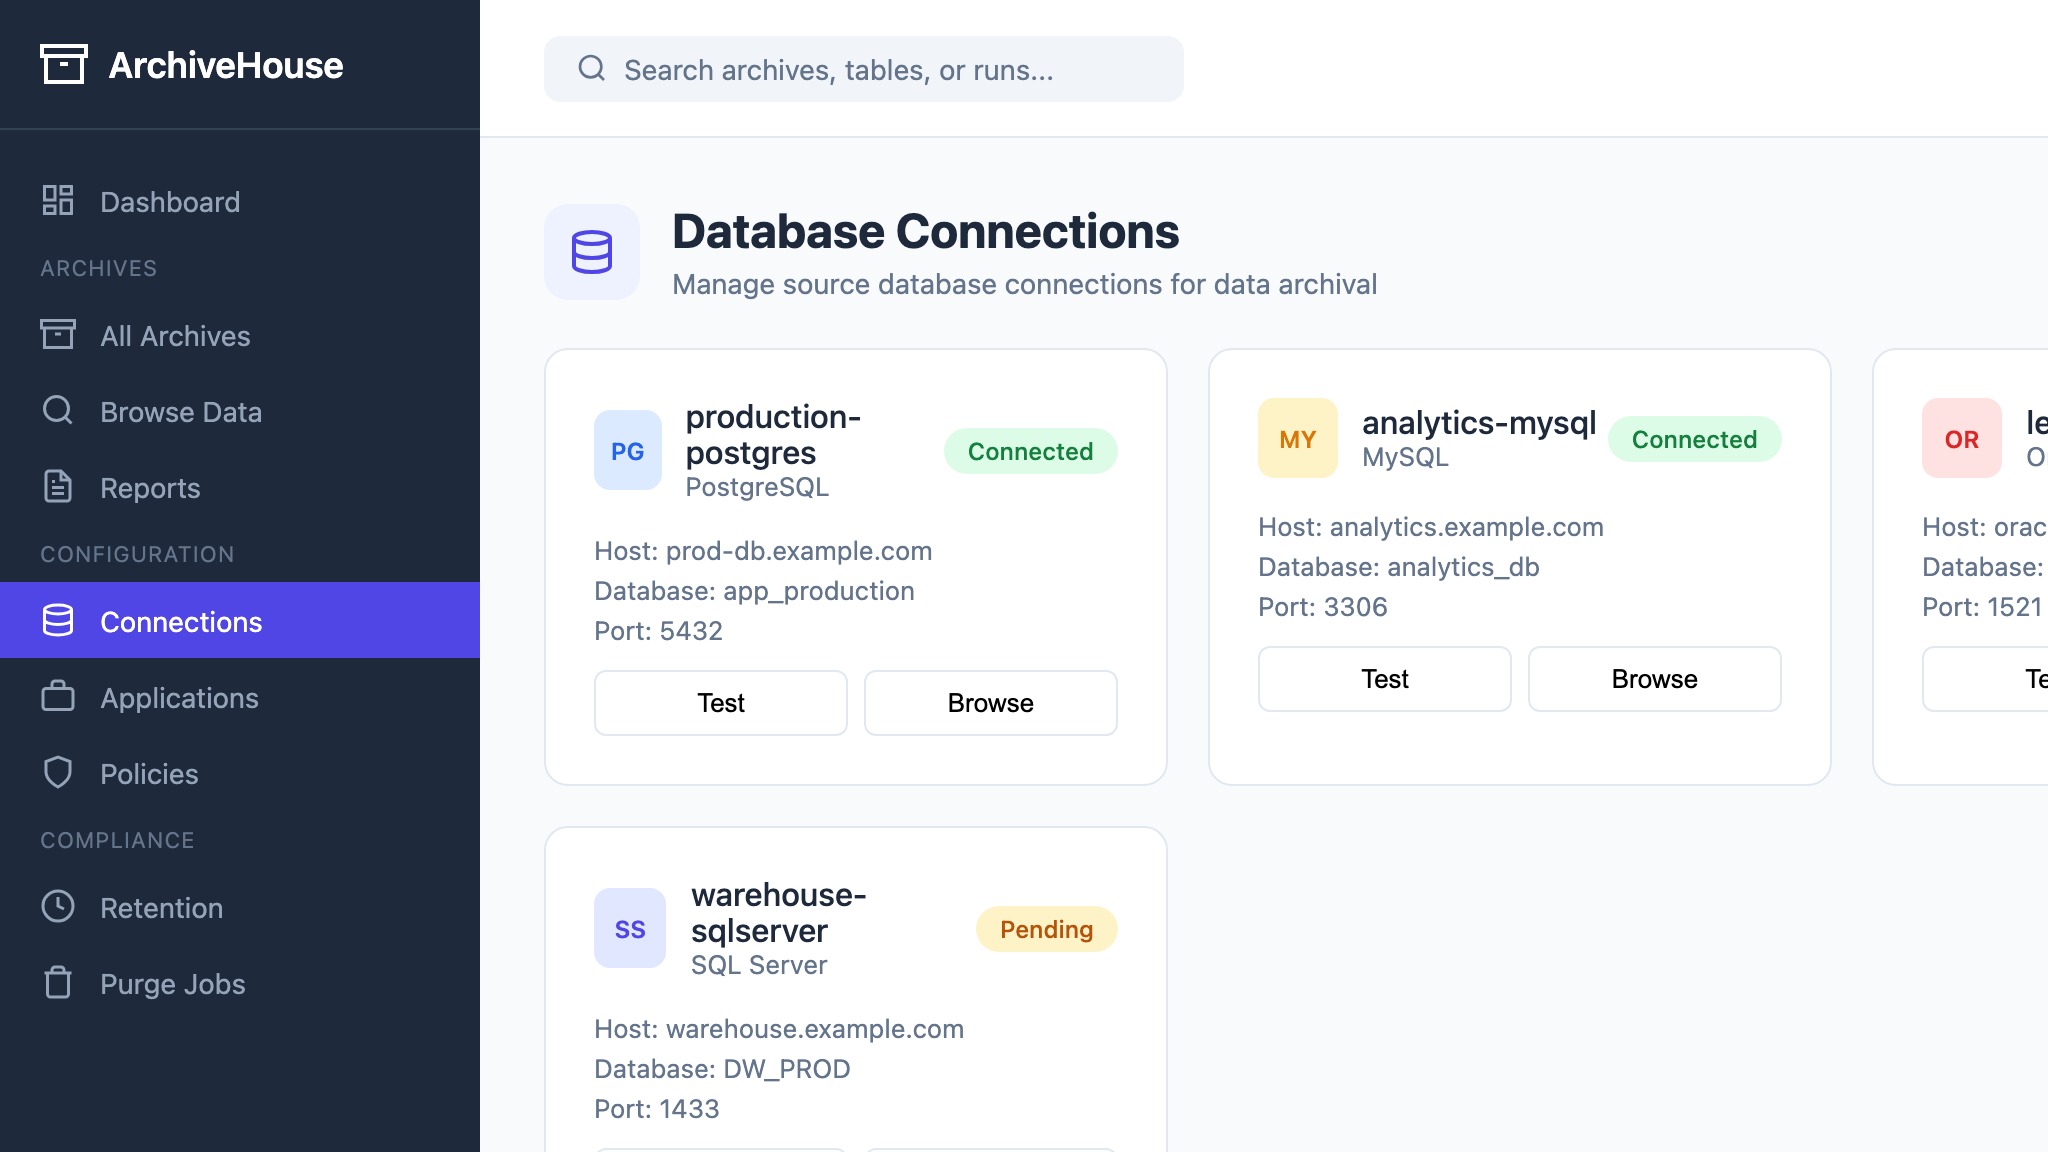
Schema Discovery
Centralized schema discovery and capture for all connected data sources with table-level metadata.
- Automated schema capture
- Table discovery & selection
- Connection testing
- Multi-database support
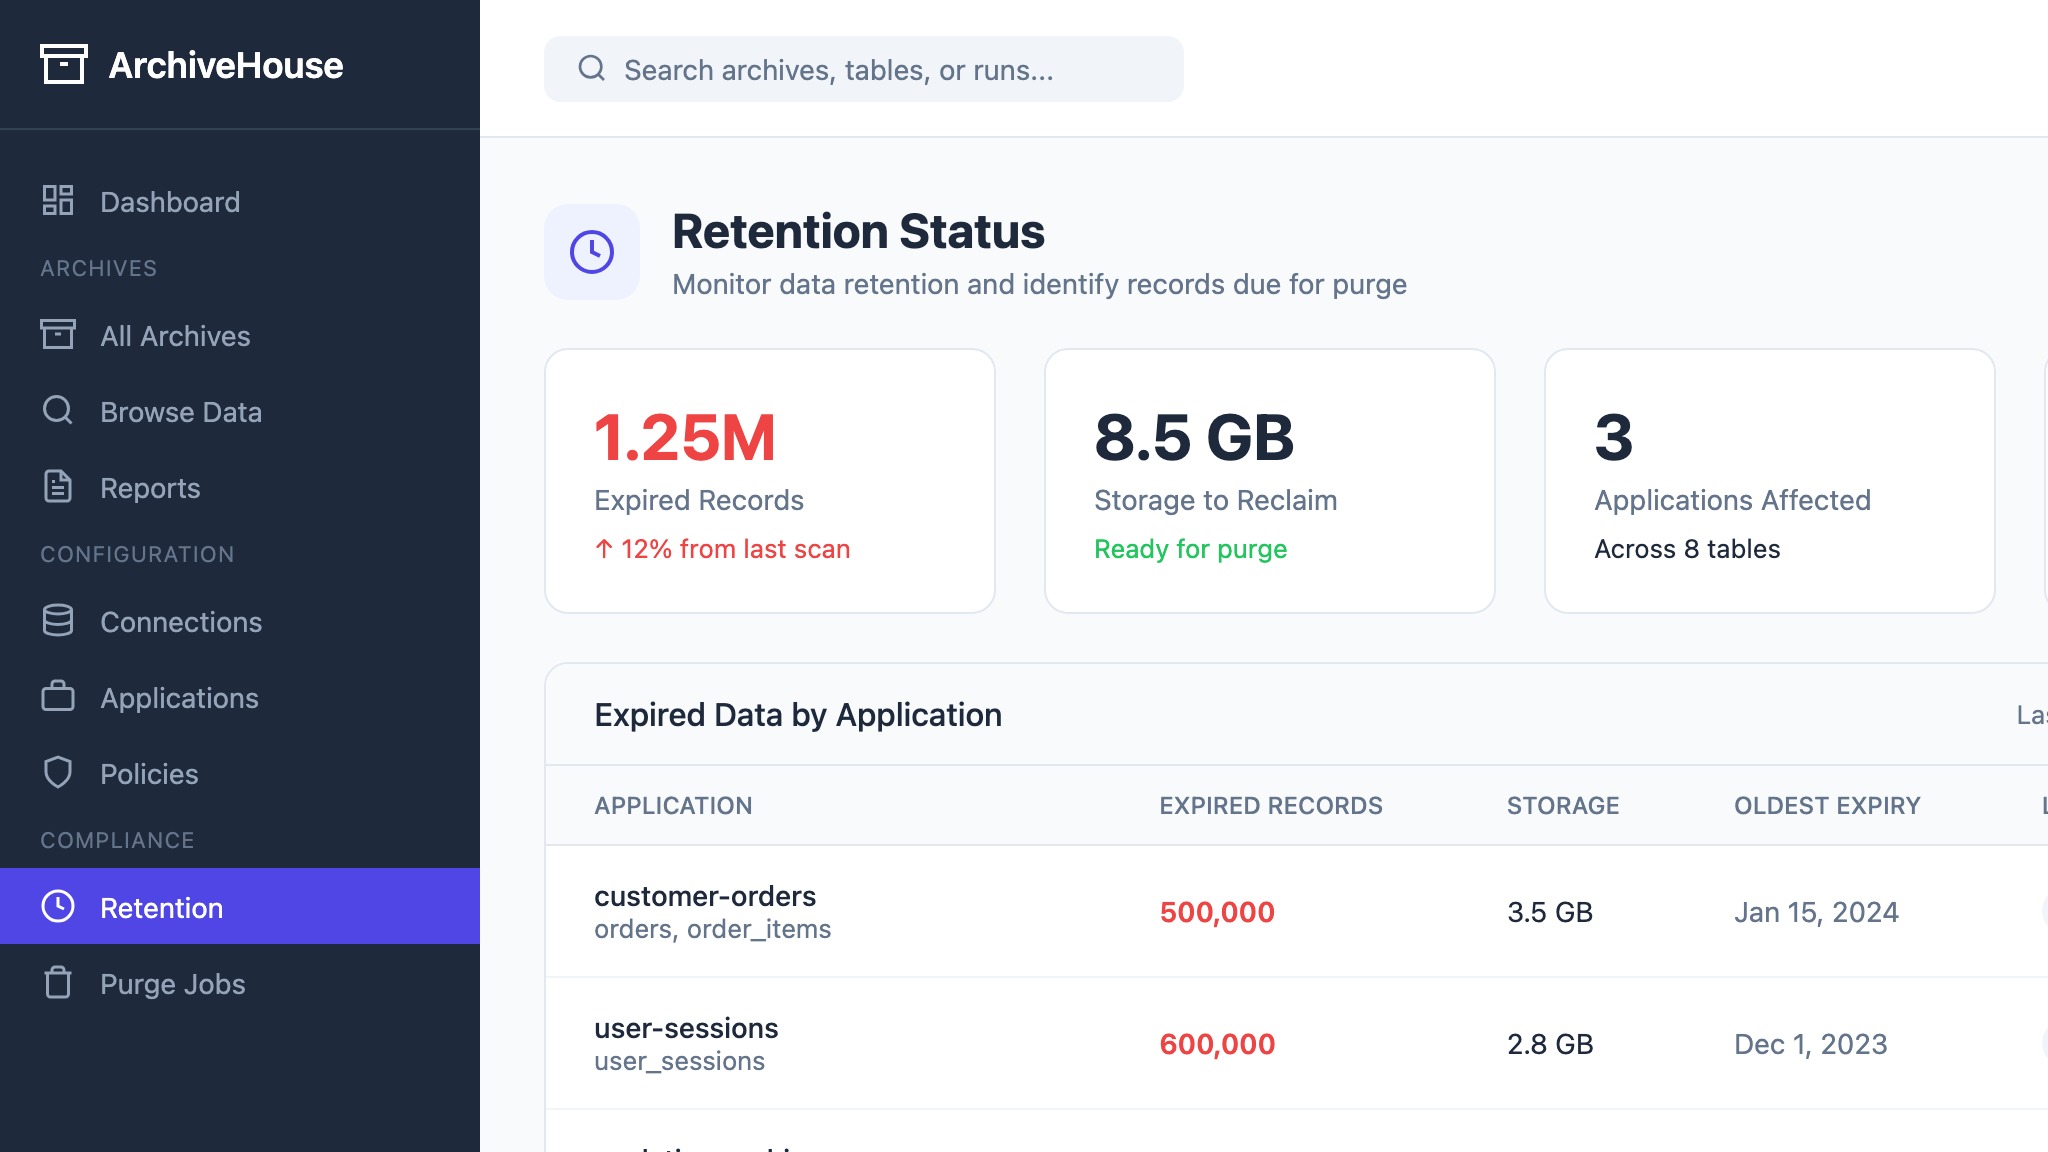
Retention Management
Automated lifecycle management with configurable retention periods, legal holds, and compliant purge workflows.
- Configurable retention periods
- Legal hold support
- Automated compliant purge
- Audit-ready deletion logs
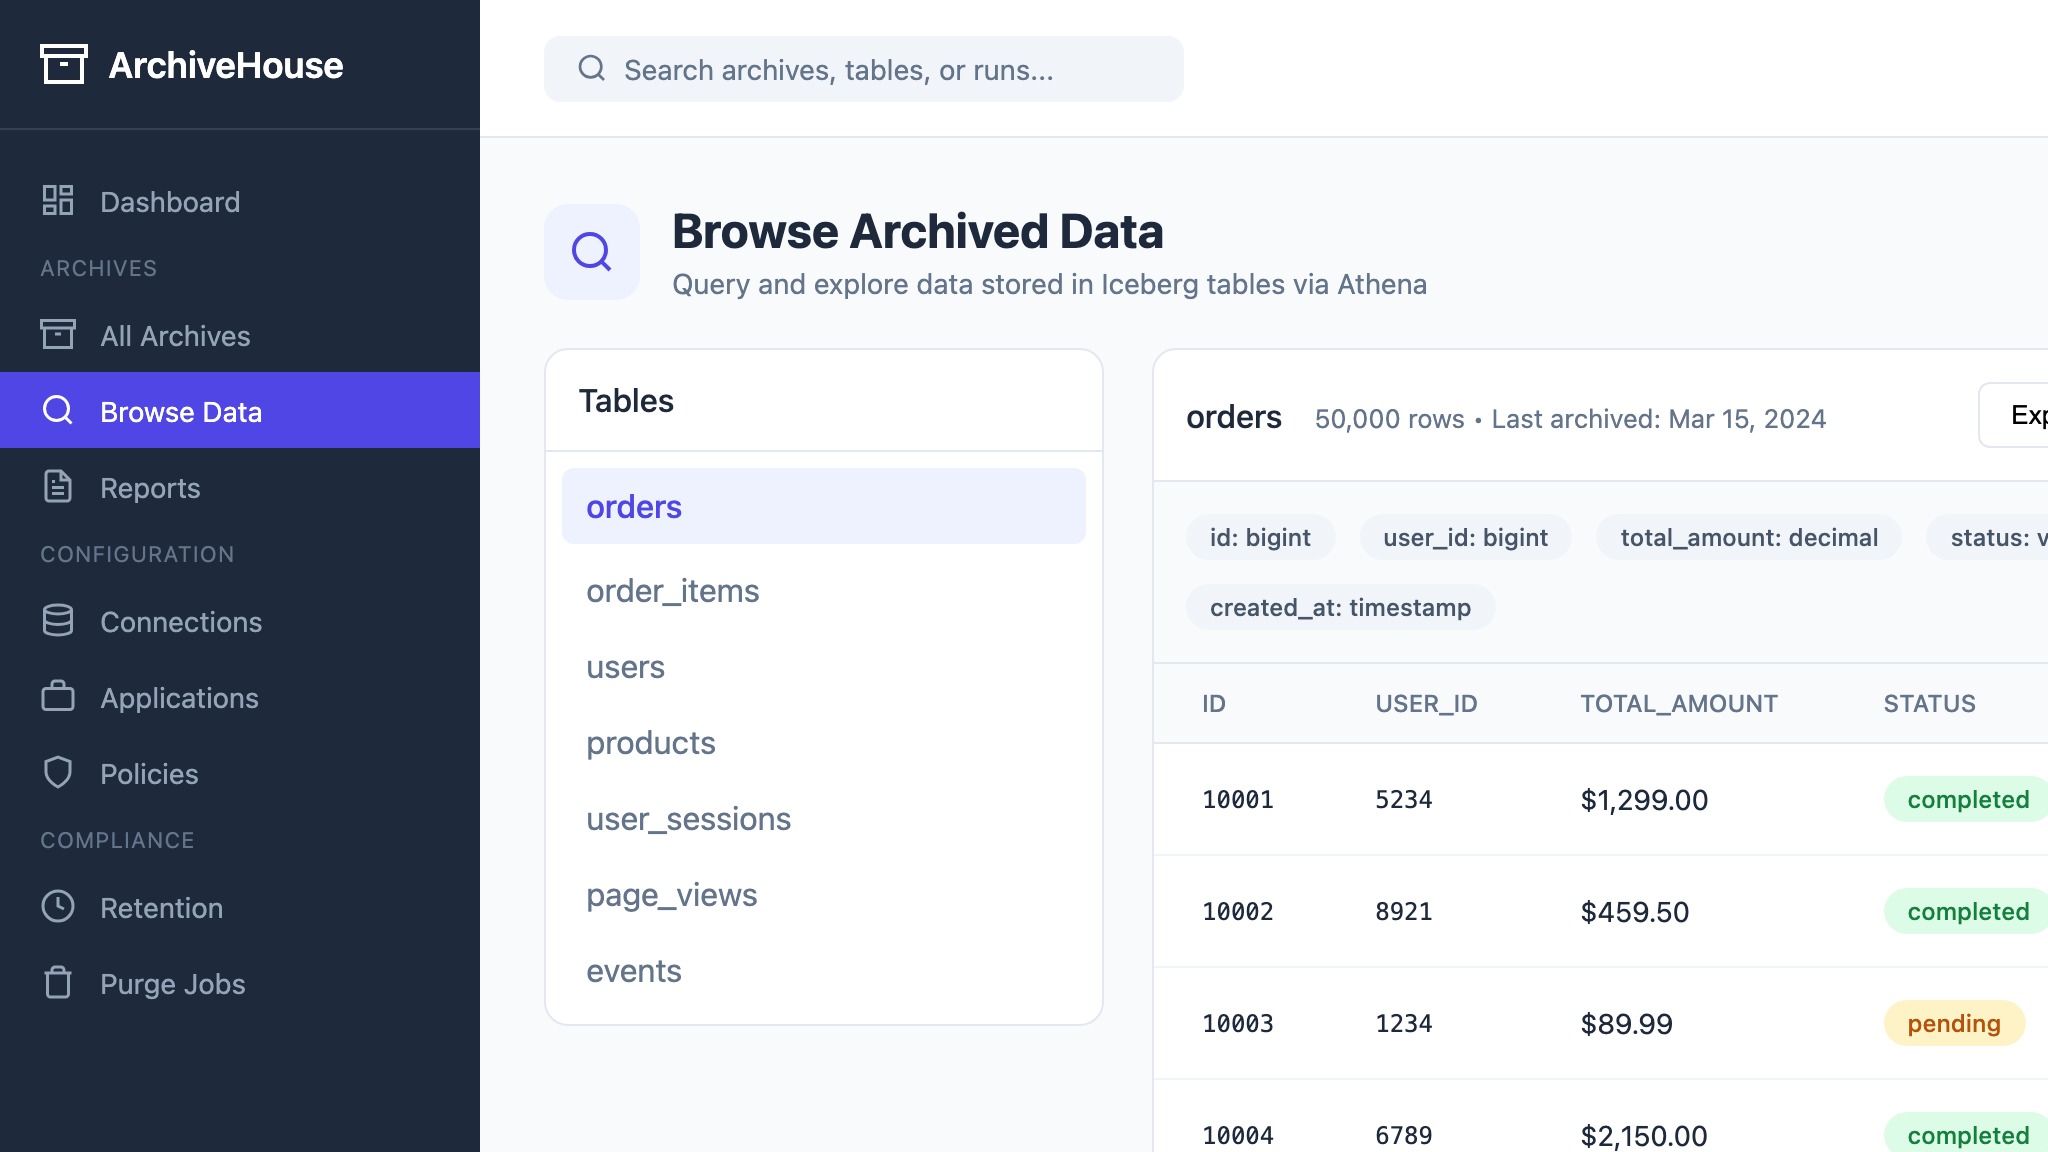
Query Layer
SQL access to archived data through Amazon Athena. Query Iceberg tables directly without data movement.
- Standard SQL via Athena
- Iceberg table format
- QuickSight integration
- Browse archived data
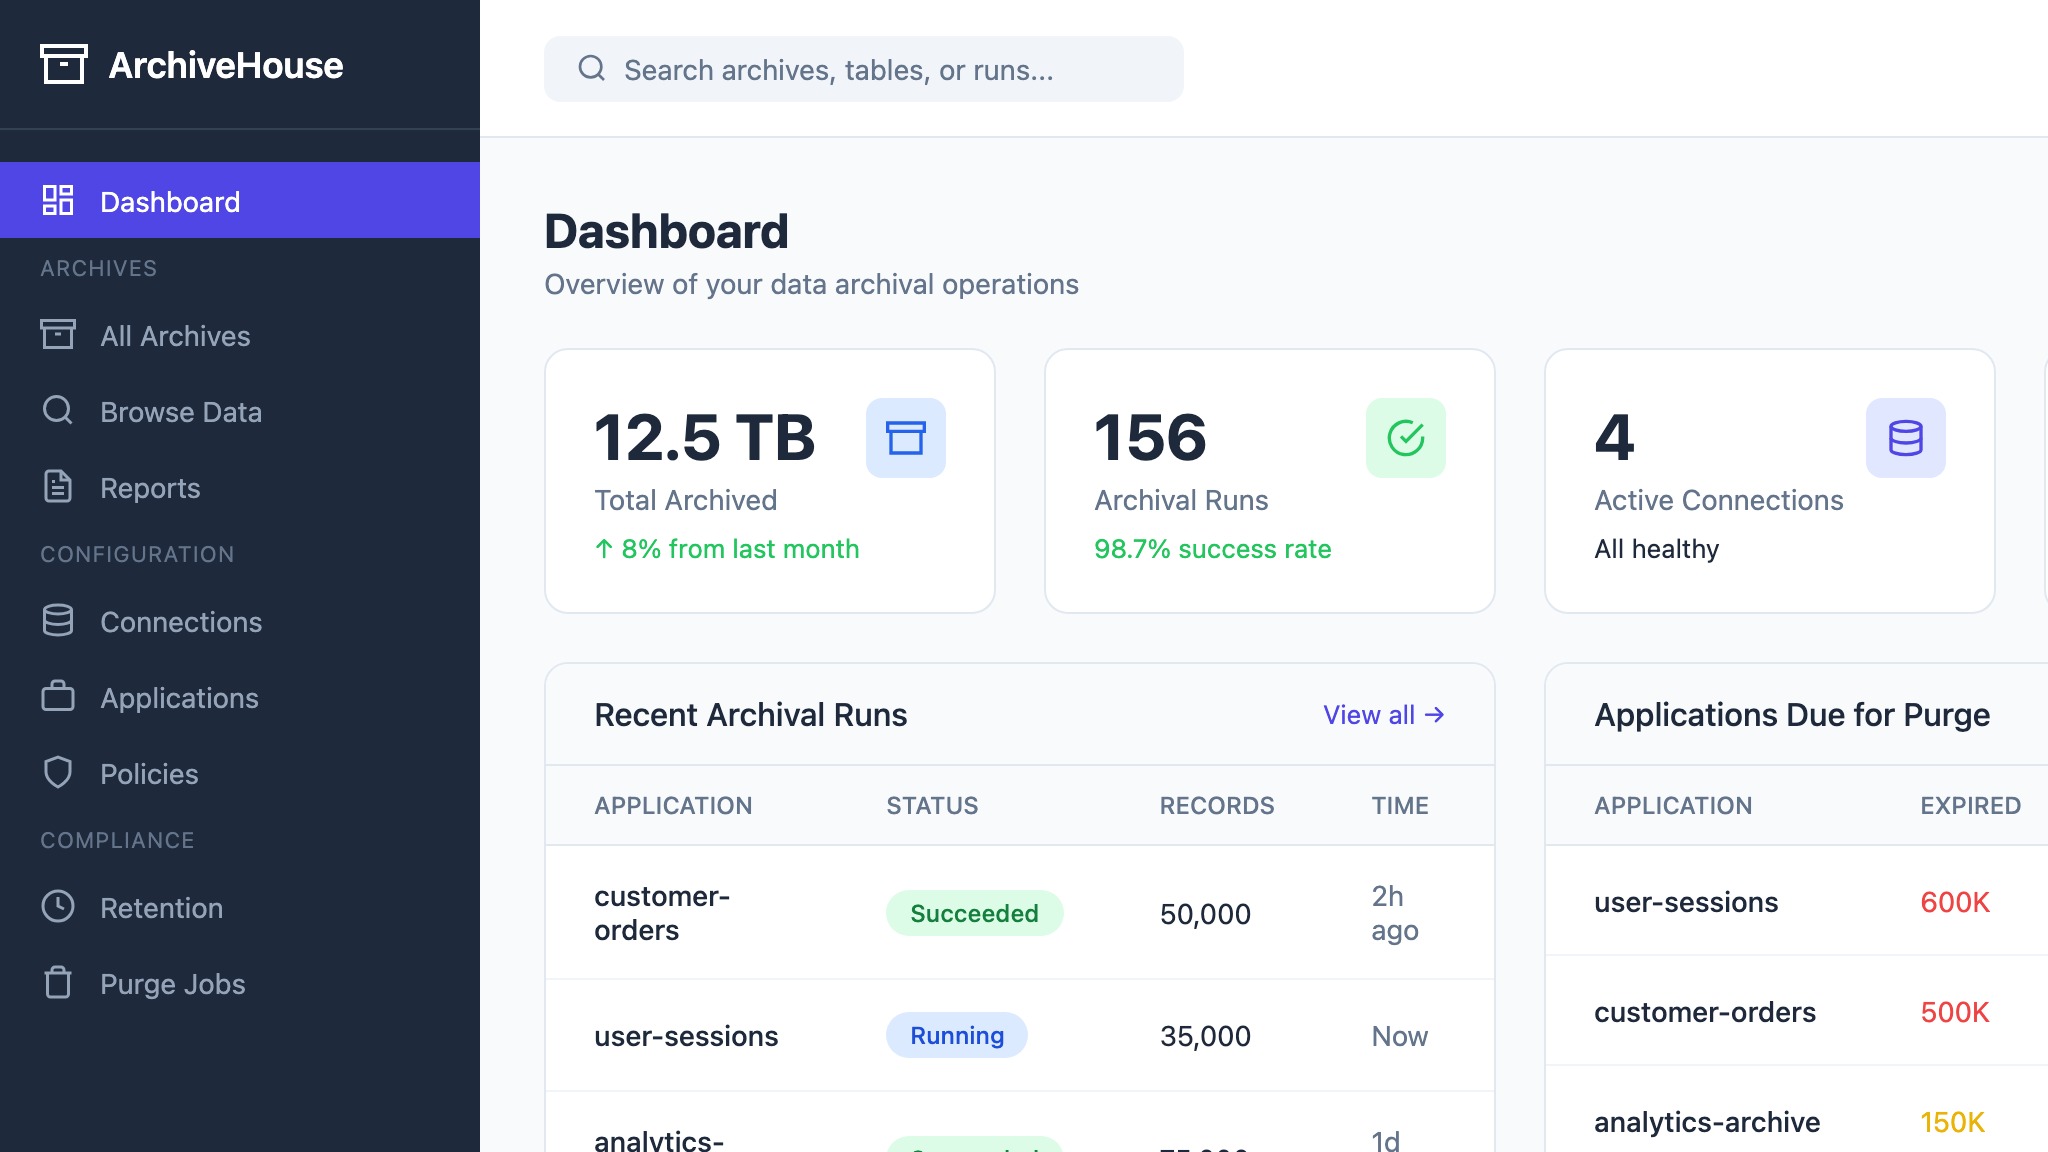
Operations Dashboard
Visibility into archival runs, retention status, purge operations, and downloadable reports across all data sources.
- Archival run tracking
- Retention status monitoring
- PDF report generation
- Run history & logs
Dynamic Data Masking
Protect sensitive data with automatic PII detection and role-based masking. Query teams see what they need—nothing more.
- Automatic PII detection
- Role-based masking rules
- SSN, email, phone & more
- Unmask with approval workflow
Policy-as-Code
Version control your data governance. Define retention, masking, and access policies in YAML. Deploy through CI/CD.
- YAML-based policy definitions
- Git-native version control
- CI/CD deployment workflows
- Drift detection & auto-sync